Amazon Transcribe: How AWS Speech-to-Text Works
A guide to Amazon Transcribe, its AWS batch and streaming workflows, speaker partitioning, media requirements, and when it fits a development project.
Amazon Transcribe is AWS’s speech-to-text service for developers. It turns media files or live audio streams into text that an AWS-based application can store, analyze, or display. It is a cloud-service building block rather than a finished transcription workspace.
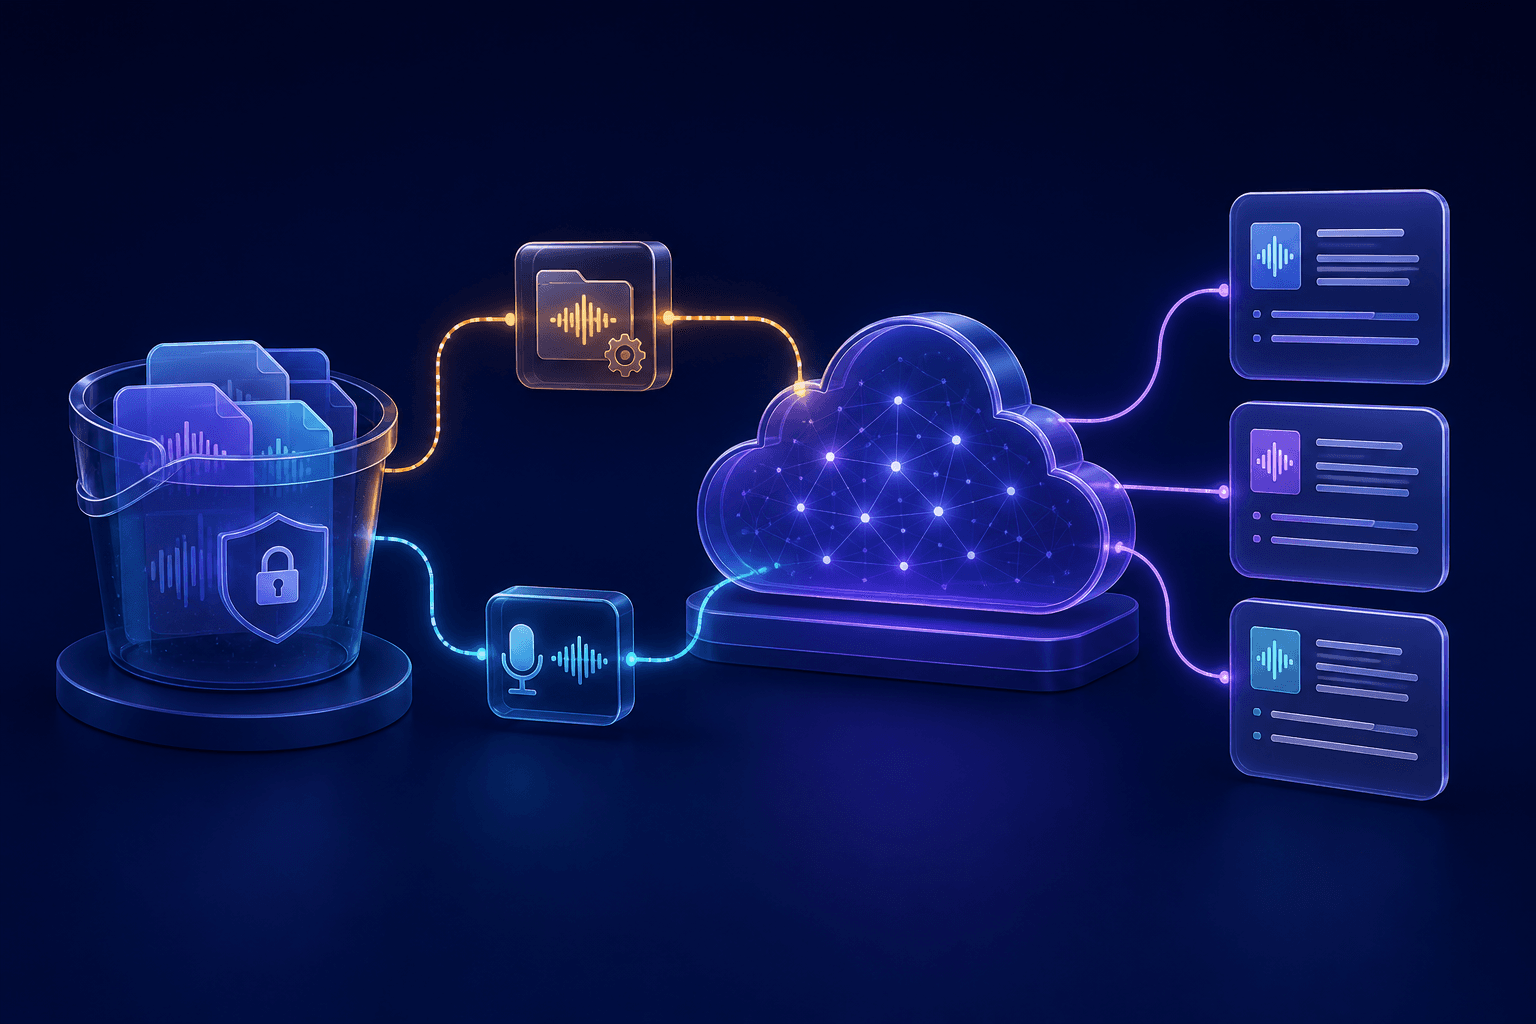
Batch files and live streams are different workflows
AWS separates batch transcription from streaming transcription. Batch jobs work with media files stored in Amazon S3; streaming sends audio to the service as it is delivered. The feature and language support can differ between those workflows, so it is important to check the relevant documentation rather than assume a setting carries across.
Speaker partitioning and channel identification
Amazon calls its diarization feature speaker partitioning. It can label speech from different people in a transcript, while channel identification is for audio where speakers are already on separate channels. AWS’s diarization guide explains the outputs and configuration.
What developers need to set up
A batch implementation commonly needs an AWS account, IAM permissions, an S3 location for input media, a job request, and logic to retrieve the result. Streaming requires an application that sends supported audio over the applicable AWS streaming interface and processes results as they arrive. AWS’s overview and media input guide are the primary references.
S3 and IAM are part of the batch workflow
For batch work, the media location and access permissions are part of the design, not just deployment details. The application needs to place or reference the input media, start and track the job, and retrieve the result according to its AWS access model. That is useful when the surrounding media pipeline already lives in AWS.
Who should use Amazon Transcribe?
It is a good fit for teams already working in AWS that need transcription as a service component, including integrations with S3-based media processing or live-streaming applications. It is not the simplest route for an individual who only needs a recording converted to a document.
When Amazon Transcribe makes sense
It makes sense for AWS-native teams that need transcription inside an S3-based media pipeline or a live-streaming application. For a direct upload-to-transcript workflow without IAM, storage, and interface orchestration, Senite transcription is a different product category. Our audio-format guide can help when choosing a source file for a transcription workflow.
Back to all articles